---
title: "Migrating our Email API to Go"
slug: migrating-our-email-api-to-go
description: "What it took to move our most critical API to Go."
created_at: "2026-11-12"
updated_at: "2026-11-12"
image: https://cdn.resend.com/posts/migrating-our-email-api.jpg
humans: ["derich-pacheco", "fabio-kubo", "bu-kinoshita", "felipe-volpone"]
featured: false
category: "engineering"
---
Rebuilding an API means preserving years of decisions, including the ones that never made it into the documentation.
For Resend, that meant matching error responses, idempotency behavior, rate limits, stored data, and the contents of the emails themselves. A faster implementation would only be useful if developers could continue relying on the behavior they already knew.
Over seven weeks and roughly **140 pull requests**, we took a new Go service from an **empty project to production traffic**.
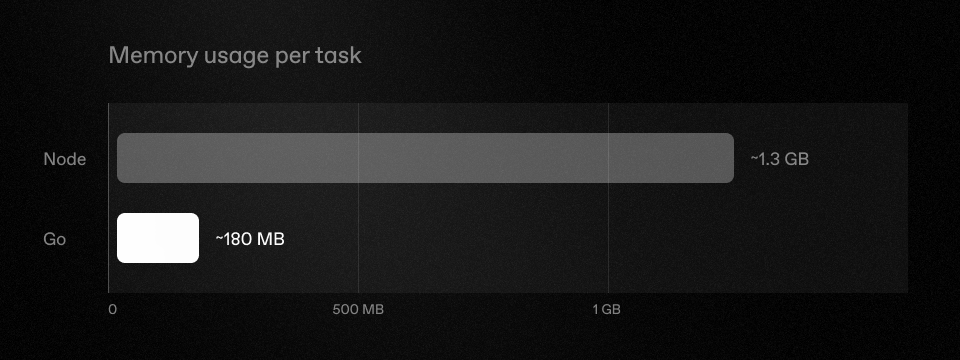
By October, Go was handling all our email API traffic. While traffic was split evenly between the two services, Go showed **roughly half the median latency and about one-seventh the memory usage** per task.
 ## Why we started
The existing Node service had failure modes we wanted to address.
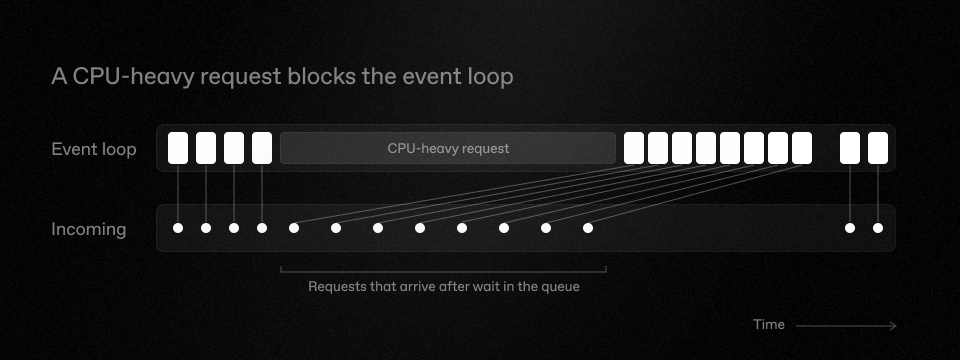
During bursts of large requests, a whole task could become unresponsive. One investigation traced this to parsing and serializing large request bodies, including requests that were already being rejected by the rate limiter.
Parsing and serializing are CPU-heavy synchronous operations in Node.js that block the event loop until they are complete. Work associated with those rejected requests could block the task from handling other traffic.
 We also saw S3 timeouts surface as customer-facing 408 and 524 errors.
**These problems shaped the requirements for the replacement**: more predictable behavior under load, lower resource usage, and better control over how long individual operations could take.
Changing the implementation also meant revisiting request handling, timeouts, connection pools, and capacity. Those decisions became a substantial part of the migration.
## Making the implementations agree
Our [engineering philosophy](https://resend.com/philosophy) calls for **predictable behavior and backward compatibility**. During a rewrite, that principle becomes a testing problem: how do you establish that two implementations behave the same way?
We built a harness that sends the same requests to Node and Go and compares their behavior. Its coverage includes responses and errors, database rows, S3 objects, idempotency, and rate limits.
Checking the HTTP response alone would leave too much untested. Both services could return a successful response while persisting different metadata or producing different email content.
**The existing implementation became a reference for compatibility.** We also preserved some Node quirks deliberately. Changing an unexpected behavior can still break an integration that depends on it.
HTML-to-text conversion was a particularly useful example. When a user sends an email with just an HTML part we convert it to text for email clients and recipients that prefer plain text emails.
The Go library we initially selected produced reasonable plain text, but its output differed from our configured Node library. Elements marked with `data-skip-in-text="true"` appeared in the Go output when they should have been omitted. Links could also gain URL text that the Node output did not include.
Those differences would change the email a recipient received.
We built a Go port of the specific HTML-to-text behavior our API uses. The initial port matched all 60 fixtures generated from the Node implementation exactly. That gave us concrete evidence for the cases covered by those fixtures, and a foundation for adding more.
## What the rollout taught us
Once we had matched the behavior of the old system, the next challenge was deploying the new system successfully. For this rollout to be a success, production required more tuning.
The new service used fewer resources per request, but we still had to double task sizes twice during the rollout.
We also made several operational changes:
- Added capacity ahead of the recurring top-of-hour traffic spike.
- Introduced per-request timeouts for S3 uploads.
- Tuned Redis connection pools as traffic increased.
**Each adjustment addressed a different constraint.** Lower average resource consumption did not tell us how much capacity a task needed during a burst. Faster request processing did not remove the need to bound storage operations or account for Redis connections.
The rollout gave us the production evidence needed to make those decisions.
## The preliminary results
These numbers come from the 50% rollout. Half of the requests went to Node and half went to Go.
Both services ran on the same task size and the Go service used about 62% less CPU per request. Median latency for `POST` requests to `/emails` fell by **roughly 50%**, while **p99 fell by about 16%**.
Much of the slow tail is time spent waiting on S3 and the database. Improving the API service reduces part of the request’s duration; further reductions at the tail require work on those dependencies and how we use them.
POST /emails median latency, "58 ms", "31 ms"],
[<>POST /emails p95 latency, "149 ms", "107 ms"],
[<>POST /emails p99 latency, "498 ms", "420 ms"],
["Batch median latency", "149 ms", "74 ms"],
["Batch p99 latency", "1,721 ms", "1,363 ms"],
["Tasks at peak", "34", "10"],
["Memory per task", "~1.3 GB", "~180 MB"],
["CPU per request (normalized)", "1.00×", "~0.38×"],
],
}}
/>
## Behind the scenes with Derich and Kubo
### 1. Before you started, what felt like the hardest part?
**Derich**: The unknown unknowns. This wasn’t a port between two similar runtimes. We went from a runtime that’s async by default to one that’s sync by default, from a permissive language to a strict one, and from types that vanish at runtime to types that don’t. So a lot of our API’s behavior lived in Node and the npm packages we used, not in our own code. Take attachments: our Node SDK accepts a `Buffer`, which `JSON.stringify` turns into `{"type":"Buffer","data":[...]}`. Node turned that back into bytes with a single `Buffer.from()` call. Go has no `Buffer`, so we rebuilt that conversion by hand, JavaScript’s coercion rules included.
**Kubo**: Every migration has its challenges, but this one was especially complex. Sending email is our most critical flow, so every change needed careful review, and we spent a lot of time building tests, adding metrics, and tuning infrastructure. On top of that, it’s a public API, which means we don’t control what reaches it: any input that worked before had to keep working. That gets harder when you move from JavaScript, which is lenient by default, to Go, which is strict. So the challenge wasn’t just returning the same HTTP response. It was making sure the email itself arrived exactly as it did before.
### 2. What’s a small detail you’re particularly proud of? Something that wouldn’t show up in the performance charts.
**Derich**: The clever code we deleted. Some of the Node service existed only to protect the event loop, where one slow request holds up every request behind it. Our email-size check, for example, had an elaborate trick to avoid scanning large bodies byte by byte. Go doesn’t have that problem, so once the port was stable, we cut the trick down to the one part that still saves real CPU. Nobody will see that in a chart, but it’s one less thing for the next engineer to untangle.
**Kubo**: One detail I’m really happy about is a simple widget showing the percentage breakdown of HTTP status codes. It gave us a quick way to see whether the new service was behaving exactly like the old one. Since we rolled out to a random percentage of requests, both services should show nearly the same status code distribution. We had plenty of tests covering validation, but that widget gave us even more confidence that everything was working as expected during the rollout.
### 3. What surprised you about working on this together?
**Derich**: The speed and autonomy we had on something this big. It was the first real project Kubo touched here, and it still felt like we’d been a team for years. We could each own a piece, run experiments, and drop the ones that didn’t work without waiting on the other. When we decided the batch endpoint should move to Go too, it went from decision to production traffic in about a week.
**Kubo**: This was my first project at Resend and my first with Derich, but from day one it felt like we’d worked together for years. We’d often talk through a solution, each of us adding something, until it was better than either of our first ideas. I think that says a lot about the culture here, and I really enjoyed working on this project.